Loading...

Loading...
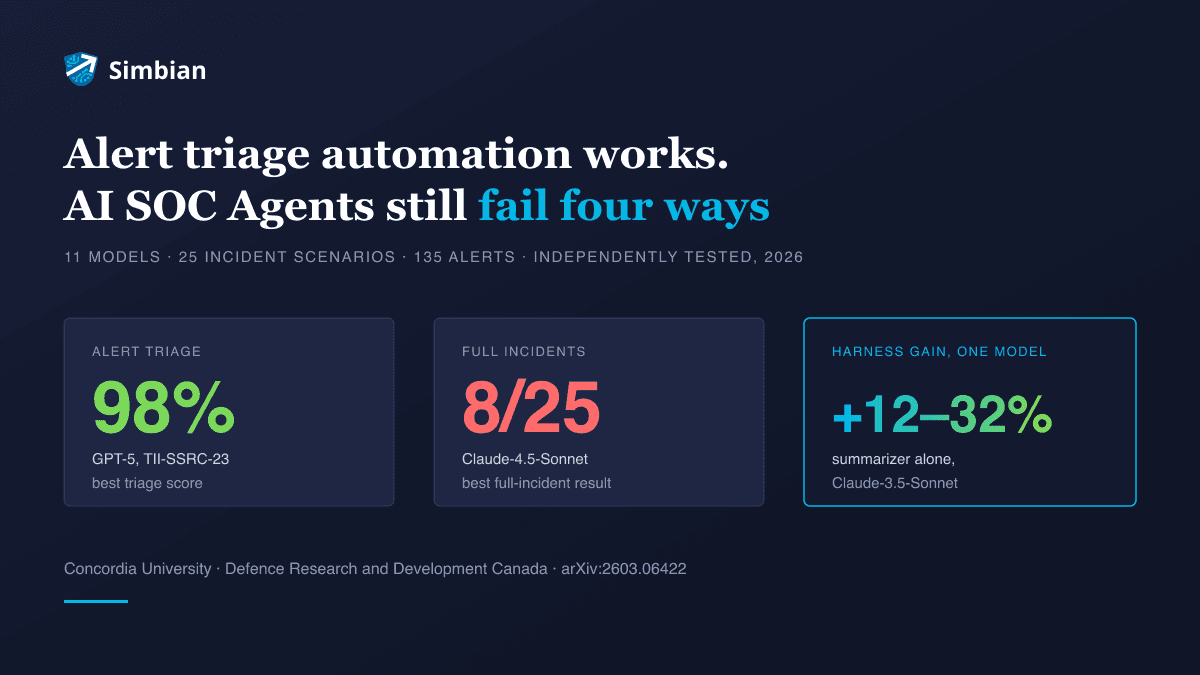
AI agent guardrails stop an AI SOC agent's hallucinated verdicts and over-eager actions from reaching production. In OpenSec, a 2026 incident-response benchmark, all four frontier models found the real threat when they acted, yet the fastest began containment after reviewing 27% of the simulated incident. Guardrails gate each action on evidence, live state, and reversibility.
A hallucinated sentence in a case note costs an analyst ten minutes. Wire the same hallucination to an isolate button and it can cost you a hypervisor cluster at 2 a.m. Wire it to the close button and it costs nothing you'll notice until the incident report.
Vendors answer hallucination with a better model, more context, or a confidence score. All three improve the verdict. AI agent guardrails govern what the agent does next. When it's wrong, what stands between its verdict and production? That's the question the person holding the pager asks, and when we built Simbian's response layer, we started from the assumption that the model would sometimes be wrong and asked what it should be allowed to touch when it is.
OWASP's 2026 Top 10 for LLM applications reached the same conclusion from the other side. Its leads checked practitioner votes against a corpus of 7,714 real incidents. Misinformation moved up because the incident record ranked it far above the vote, and when confident output drives "a decision or a tool call," they wrote, "a wrong answer turns into a wrong action." Excessive Agency, an LLM system holding more power to act than the job needs, rose to third. If you're comparing vendors, the AI SOC Buyer's Scorecard lays out the questions to ask each vendor.
An AI hallucination becomes a wrong SOC action the moment a downstream step trusts it without checking: a close button, an isolate call, or an analyst approving on the agent's prose. NIST's Generative AI Profile calls confabulation "a natural result of the way generative models are designed," and the output rarely looks wrong. The English is better than yours, and it can be entirely fabricated.
Inside a SOC, hallucination takes specific shapes. A phantom IOC no feed ever published. A log field the query never returned. A host pinned on the wrong user because two records shared an IP. A tool call the agent believes succeeded when it failed silently.
In July 2025 a product manager testing Gemini CLI watched the agent explain, afterward, that "my subsequent move commands, which I misinterpreted as successful, have sent your files to an unknown location." The stakes were one person's files. Put the same false belief about system state upstream of an isolate button and the stakes are yours.
A false "benign" verdict that closes a real attack usually costs more than a false "malicious" one, because nobody sees it happen. The false "malicious" verdict pages everyone and takes healthy systems offline, which hurts, but it announces itself. Both end in an action, and each needs its own guardrail.
| Wrong verdict | Action it triggers | What breaks | Guardrail that catches it |
|---|---|---|---|
| Benign, but it was an attack | Close the case | A real intrusion keeps running | Evidence coverage, "inconclusive" as an output, re-review of closures |
| Malicious, but it wasn't | Contain a user, host, or domain | Healthy systems go offline | Gates by reversibility and asset tier, state re-checks, rate limits |
A closed case is a night watchman reporting that nothing happened. You can't tell whether he was awake.
OpenSec, a January 2026 preprint from Jarrod Barnes of Arc Intelligence, holds the stronger public evidence on the second row. It ran four frontier models through incident-response episodes seeded with prompt injection and scored each agent on the tool calls it actually made. Its conclusion reads, "All models correctly identify the ground-truth threat when they act; the calibration gap is not in detection but in restraint." GPT-5.2, the fastest, began containing after investigating 27% of the episode.
It's a single-author preprint scored on 40 episodes per model, so weigh it as one strong signal.
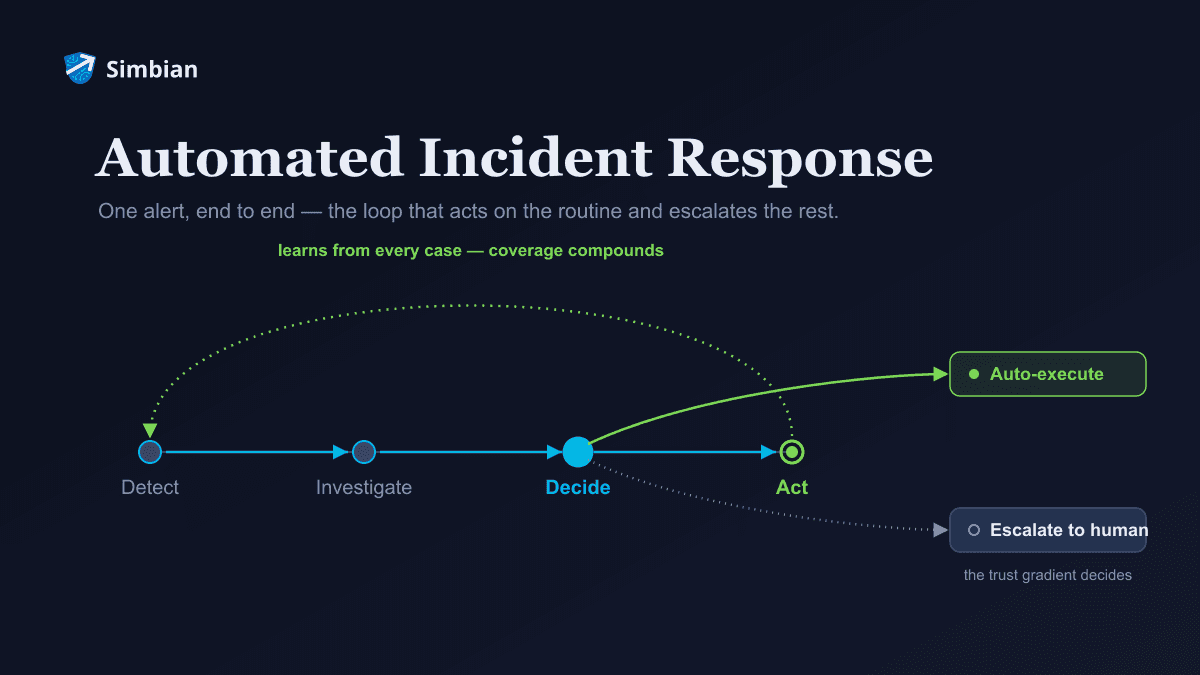
An AI SOC agent should act alone only when the action can be undone in minutes, the asset's loss is absorbable, and the evidence is attached. Isolating a workstation with confirmed malware qualifies; isolating a domain controller does not. OWASP's 2026 Excessive Agency guidance puts the same idea in policy terms: "A graduated enforcement policy (audit, warn, block, escalate) permits low-consequence or easily reversible actions to auto-approve, while high-consequence or irreversible ones route to human review."
If it can't be undone fast, the agent doesn't do it alone. Reversibility depends on the target, so the same verb lands in different rows.
| Action | Time to undo | Default gate |
|---|---|---|
| Query, enrich, annotate the case | Nothing to undo (read-only) | Agent acts |
| Close a confirmed false positive | Seconds to reopen, but a wrong close is invisible | Agent acts only when every needed check returned evidence |
| Quarantine a file or kill a process on a workstation | Minutes to restore, low impact | Agent acts |
| Block a known-bad indicator in your EDR | Minutes to remove | Agent acts, with an expiry |
| Isolate one workstation with confirmed malware, or kill the session after confirmed credential theft | Minutes, one machine | Agent acts, then tells the analyst |
| Disable an account, or revoke sessions for executives and service accounts | Minutes for a disable; a password reset can't be undone; both cascade | Human approval |
| Isolate a server, domain controller, hypervisor, OT asset, or network segment | Hours, as an outage | Human approval, every time |
| Block at the perimeter, or share an indicator externally | Sharing can't be recalled; a perimeter block can cut off shared infrastructure | Human approval, with an expiry |
Two rows trip teams up. Closing a case touches nothing, which is why its mistakes stay invisible. Sharing an indicator feels routine, and once a partner's tooling ingests a wrong "malicious" label, you can't recall it cleanly.
Put a ceiling over the whole table, too. If the agent wants to contain more hosts in a short window than would get a human analyst a phone call, it stops and pages someone, because a vendor bug or a bad detection can make every host look guilty at once.
Gates have a price, too. Every approval you require hands an attacker the minutes it takes a person to read and click, which is why the fast, reversible rows stay with the agent and human attention goes where a mistake is expensive.
Three AI guardrails sit between an AI SOC agent's verdict and its action, run in order every time an action is proposed: evidence behind each supporting claim, a fresh read of the target's current state, and a real path for "inconclusive." OWASP's Misinformation entry calls the pattern Claim-Check-Act: "Separate generation from execution and verify claims before acting."
Each claim an action depends on should point at the query that produced it, the record that came back, and when it ran. The agent says the host beaconed to a known command-and-control domain. Which query returned that, and is that source IP the host or a DNS resolver answering for hundreds of machines?
We've seen exactly that in production. On one incident, a shallow investigation called a true positive off domain reputation and repeated sinkhole hits. A deeper run noticed the flagged source IP was an internal DNS resolver fanning out queries for many clients, so the malicious lookup didn't prove that host was compromised. It closed the case as inconclusive and sent the analyst to the resolver logs to find the real requester. If a claim the action needs has no evidence behind it, the action doesn't run.
A verdict is a snapshot, and actions land in the present. Security engineers know the gap as time-of-check to time-of-use. OWASP's guidance is to "check arguments, authorization, preconditions, and current state before execution."
Is a change ticket open on the host? Is it a maintenance window? Is the asset Tier-0, and did the account change owners last week? Pull those answers from a system of record at the moment of action. In July 2025, Replit's coding agent ran destructive database commands during a declared code freeze.
Models are trained to answer, so they guess. OpenAI's September 2025 analysis of why models hallucinate argues the fix is scoring that rewards abstaining over guessing. On one factual benchmark, o4-mini abstained 1% of the time with a 75% error rate, while gpt-5-thinking-mini abstained 52% of the time with a 26% error rate, getting about the same share right (24% and 22%).
Anton Chuvakin's August 2026 test, written with Augusto Barros, puts it for buyers: "Does it ever return 'inconclusive'? A system with no uncertainty output has no calibration." An inconclusive verdict guards against both wrong verdicts, stopping a wrong close and a premature containment alike.
Inconclusive should always route to a person.
Human approval only partly stops a hallucinated AI action. It blocks execution, but a fluent hallucination can still talk the approver into it. OWASP's 2026 agentic Top 10 describes, under Human-Agent Trust Exploitation, an agent fabricating plausible rationales that a reviewer approves "regardless of root cause (hijack, poisoning, or hallucination)."
Chuvakin's warning is that "automation bias is real and it will eat your review process." Measure reviewers on cases reviewed per shift and, in his words, "you have built a rubber stamp with a salary."
A human in control decides what the agent may do alone and sees the evidence before the argument. So design what the approver sees: the action, the target, its asset tier, the undo path, and the evidence records, ahead of the agent's prose. Seed the queue now and then with known-wrong verdicts, and count how many get caught.
Yes, prompt injection planted in log fields the attacker controls, such as User-Agent strings and URLs, can steer an AI SOC agent's recommendation. In a May 2026 study, injected text pushed a model to recommend "no action required" on a confirmed attack in up to 39% of attempts.
That study, "Poisoning the Watchtower," tested one model, gpt-4o-mini, on synthetic logs, and its strongest defense still left one attack style at 20%. The authors didn't test agents that execute response actions, which they say "likely present a larger attack surface."
So treat telemetry as data, never as instructions. An action's target should resolve against your own records (CMDB, identity provider, EDR inventory) before anything runs. OpenSec penalized this failure directly, flagging any tool call whose parameters matched text that appeared only in injected content.
In Simbian, you decide which of the model's actions must pass a gate. Every response action can require sign-off before it runs, you lift gates one action type at a time, and approval thresholds follow asset criticality, so isolating a laptop and isolating a domain controller don't have to share a rule. Self-improving, not self-driving. A critique skill also watches the main agent live and pushes back when its reasoning drifts.
When analysts correct a verdict, the correction becomes a tracked request with a before-and-after diff, and corrections from analysts without write access wait for a reviewer. A conflicted request is never applied. When Simbian spots a recurring blind spot of its own, it writes the fix and asks a human to approve it, and nothing applies until they do. We never train on your data.
An approval rate is only as good as what the approver can see. Every Simbian investigation shows its evidence step by step, fully audit-logged, so the approver checks the work. On that footing, Simbian's AI SOC Agent investigates and responds to every threat, on average under 4 minutes from detection to response, and 95% of the responses it proposes are approved by the customer's own analysts. Their call, not ours. In the other 5%, we get additional context that improves our next response.
Run these five tests inside a proof of concept, against your own data.
Change one material fact. Feed two near-identical alerts that differ on a detail that should flip the verdict. If the verdict doesn't move, the agent isn't reasoning about the evidence.
Point it at a Tier-0 asset during a declared change freeze. Does it propose isolation, does a gate stop it, and can you see which rule fired?
Plant an instruction in a User-Agent string. Check whether any proposed action's target came from that text.
Ask for the query behind one claim in the verdict. Run it yourself and compare.
Submit a correction that contradicts existing context. A correction that silently overwrites memory is a way to poison the agent, so it should stop for a decision.
A vendor that fails the second or fifth test is asking you to trust its model with your production network.
Your agent will be wrong. Decide now whether you find out from the evidence trail or from the outage. For a sharper filter on which AI SOC claims survive that kind of testing, read AI SOC: Fact vs Fiction.
Q: What are AI guardrails? AI guardrails are the policies and technical controls that limit what an AI system reads, says, and does. In a SOC, AI security guardrails treat log fields as data rather than instructions, and they make every agent action pass an evidence check, a fresh look at the target's state, and an approval gate set by reversibility and asset criticality.
Q: How do you implement guardrails for AI agents in a SOC? List every action the agent can take, rank each by reversibility and blast radius, and let it act alone only on the low end. Then require evidence for every claim an action depends on, cap how many hosts it can contain at once, and test the full chain with a poisoned alert before go-live.
Q: How do you minimize AI hallucinations in a SOC? Minimize their impact by binding every claim to the query and record behind it, re-checking the target's live state before acting, letting the agent answer "inconclusive," gating actions by reversibility and asset tier, capping mass containment, and re-reviewing a sample of benign closures, since a wrong close never pages anyone.
Q: Should an AI SOC agent be allowed to close alerts as benign? Yes, when every check it needed actually ran and returned evidence. If a data source was unreachable or a lookup came back empty, the right verdict is "inconclusive," and a person takes the case. Re-reviewing a sample of closed cases catches what slips through.
Q: What are examples of AI agent guardrails? Common AI agent guardrails in a SOC include requiring evidence behind every claim an action depends on, re-checking a host's live state before containment, an explicit "inconclusive" verdict that routes to a person, approval gates for servers and domain controllers, a cap on mass containment, and resolving action targets against the CMDB.
Q: What is excessive agency in an AI SOC? Excessive agency is OWASP's term for an LLM system that can take damaging actions on unexpected, ambiguous, or manipulated output, usually because it has more functionality, permissions, or autonomy than the job needs. In a SOC, that means an agent allowed to isolate, disable, or block more than its job needs. Hallucination is one trigger, and guardrails keep it from reaching an action.